PUBLISHER: Mordor Intelligence | PRODUCT CODE: 2154504

PUBLISHER: Mordor Intelligence | PRODUCT CODE: 2154504
Synthetic Data Services For Enterprise AI - Market Share Analysis, Industry Trends & Statistics, Growth Forecasts (2026 - 2031)
According to Mordor Intelligence, the synthetic data services for enterprise AI market size is projected to expand from USD 0.42 billion in 2025 to USD 0.55 billion in 2026, and to USD 2.27 billion by 2031, registering a CAGR of 32.77% between 2026 and 2031.
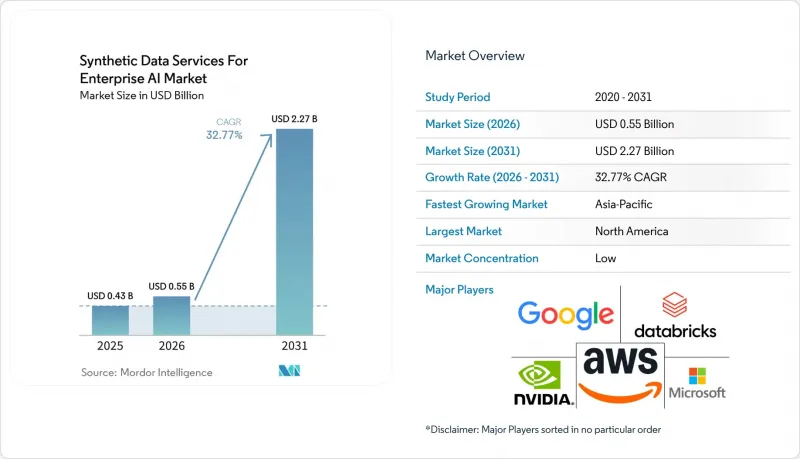
Global Synthetic Data Services For Enterprise AI Market Trends and Insights
Generative AI Training Data Shortages Drive Synthetic Pipeline Investment
The Synthetic data services for enterprise AI market benefits when enterprises lack sufficient real data for model training. Public data is increasingly irrelevant to specialized business tasks, while proprietary records are often too limited or restricted for broader use. Financial institutions and healthcare providers face the strongest combination of data value and privacy limits. This makes generated data useful both for expanding training volume and for retaining control of sensitive records. Enterprises also use it to create labeled examples that would be expensive to collect manually. The Synthetic data services for enterprise AI market gains when suppliers can demonstrate that generated records remain suitable for the intended model task.
Privacy-Preserving Access to Sensitive Enterprise Data Becomes a Compliance Mandate
Stricter expectations for personal-data protection support the Synthetic data services for enterprise AI market. The European Data Protection Board stated that an AI model cannot be considered anonymous if personal data can be extracted from it, thereby raising the standard for privacy claims. Germany's data protection conference recommended synthetic and anonymized data as technical and organizational measures for AI development in its June 2025 guidance. The Financial Conduct Authority has also set out governance considerations for the use of synthetic data in financial services. These requirements shift buyer attention from simple data generation to evidence of privacy, security, and governance. Providers with auditable processes are better placed in regulated procurement.
High Compute and Infrastructure Costs Constrain Mid-Market Adoption
High-fidelity generation can limit adoption within the Synthetic data services for enterprise AI market. Image, video, and multimodal sensor data require considerable computing capacity. Smaller organizations may struggle to run generation and evaluation pipelines at the volume required for production use. This issue is especially relevant when teams must preserve privacy while generating large test datasets. Financial institutions also face limits on the use of production data in testing environments, which can increase the need for alternatives. Consumption-based services can reduce the initial commitment, but they do not remove the cost of large workloads.
Other drivers and restraints analyzed in the detailed report include:
- Rising Demand for AI Model Testing and Validation Unlocks Non-Training Revenue Streams
- Autonomous Systems and Digital-Twin Simulation Create a Physics-Rich Data Tier
- Uncertain Legal Treatment of Synthetic Data Creates Governance Overhang
For complete list of drivers and restraints, kindly check the Table Of Contents.
Segment Analysis
Tabular data held 41.18% of revenue in 2025, giving it the leading position in the Synthetic data services for enterprise AI market. Financial risk models, healthcare records, and insurance workflows require records that preserve useful statistical patterns. The FCA worked with the Alan Turing Institute to create a synthetic retail banking dataset that includes anti-money-laundering scenarios. Text and natural-language data also help companies adapt models to confidential documents, while time-series and audio data support narrower industrial and voice applications. These uses make privacy controls, practical utility, and reliable evaluation central to buyer decisions.
Image and video data are forecast to grow at a 33.28% CAGR through 2031. This part of the Synthetic data services for enterprise AI market supports computer vision, robotics, and vehicle development programs that require scenes that are difficult to collect safely. Simulation can provide consistently labeled examples across large datasets and varied operating conditions. NVIDIA's Cosmos platform reflects the shift toward a generation that accounts for physical behavior and multiple sensor types. Visual data suppliers compete on sensor consistency and scenario realism, rather than image quality alone.
Synthetic data generation platforms captured 60.48% of revenue in 2025. The Synthetic data services for enterprise AI market industry serves organizations with in-house data engineering teams through software for generation, quality assessment, and workflow integration. MOSTLY AI released an open-source Synthetic Data SDK under the Apache 2.0 license in January 2025, enabling organizations to generate data inside their own infrastructure. Open tooling increases the importance of governance and lineage functions for commercial providers. Tonic AI, Syntho, and K2view compete in test data management, relational synthesis, and enterprise connectors.
Professional and managed services are forecast to grow at a 33.39% CAGR through 2031. The Synthetic data services for enterprise AI market also serves buyers that need external help with program design, privacy review, and operation. This pattern is most visible in healthcare, financial services, and public-sector work, where accountability and service levels are important. Managed delivery can help teams integrate generated data into existing governance practices. It does not eliminate the need for customer oversight of data quality and permitted use.
Complete Report Scope:
- By Data Type
- Tabular Data
- Text and Natural Language Processing Data
- Image and Video Data
- Other Data Type
- By Offering
- Synthetic Data Generation Platforms
- Professional and Managed Services
- By Application
- AI and Machine Learning Training and Development
- Test Data Management
- Data Sharing and Monetization
- Data Analytics and Visualization
- Autonomous Systems and Robotics Simulation
- Other Applications
- By End-User Industry
- Banking, Financial Services and Insurance
- Healthcare and Life Sciences
- Automotive and Transportation
- Retail and E-Commerce
- Information Technology and Telecommunications
- Manufacturing and Industrial Automation
- Other End-User Industries
- By Geography
- North America
- United States
- Canada
- Mexico
- South America
- Brazil
- Argentina
- Chile
- Rest of South America
- Europe
- Germany
- United Kingdom
- France
- Italy
- Spain
- Rest of Europe
- Asia-Pacific
- China
- Japan
- India
- South Korea
- Australia
- Rest of Asia-Pacific
- Middle East
- United Arab Emirates
- Saudi Arabia
- Qatar
- Rest of Middle East
- Africa
- South Africa
- Egypt
- Nigeria
- Rest of Africa
- North America
Geography Analysis
North America accounted for 41.34% of revenue in 2025, representing the largest regional share in the Synthetic data services for enterprise AI market. The region combines major cloud and AI infrastructure with enterprises developing AI systems. SAS launched SAS Data Maker on the Microsoft Marketplace in November 2025, expanding access to its synthetic-data tooling for Azure customers. The United States has major activity in autonomous systems, financial services, and enterprise software testing. Canada adds financial services use cases, while Mexico drives demand for manufacturing-related digital twins.
Privacy obligations and AI development goals shape Europe's demand. Germany's 2025 guidance recommended synthetic and anonymized data for AI systems. Syntho joined the University of Amsterdam-led ELSA Lab initiative for fair and inclusive healthcare AI in April 2025. The FCA opened applications in March 2026 for its Synthetic Data Anti-Money Laundering Solution Sprint. The EU AI Act's high-risk AI obligations take effect in August 2026, increasing the need for documented provenance and auditability.
Asia-Pacific is forecast to grow at a 33.41% CAGR through 2031. The Synthetic data services for enterprise AI market is supported by automotive development, financial-sector adoption, and national AI programs. CUBIG completed a Series A round in August 2025 and identified Kyobo Life Insurance and IBK Enterprise Bank among its customers. Tier IV and Astemo announced a joint autonomous-driving AI platform in August 2026 that includes large-scale synthetic data generation. South America is supported by fintech and open-banking use cases, particularly in Brazil. The Middle East and Africa remain early in adoption, although national AI programs in Saudi Arabia and the United Arab Emirates support public-sector demand.
- Amazon Web Services, Inc.
- Microsoft Corporation
- NVIDIA Corporation
- Google Inc
- International Business Machines Corporation
- Databricks, Inc.
- MOSTLY AI GmbH
- Gretel Labs, Inc.
- Synthesis AI, Inc.
- Tonic AI, Inc.
- GenRocket, Inc.
- Hazy Limited
- Datagen Technologies Ltd.
- Parallel Domain, Inc.
- Rendered.ai, Inc.
- MDClone Ltd.
- Syntho B.V.
- Betterdata Pte. Ltd.
- K2view Ltd.
- Informatica Inc.
- Sogeti S.A.
Additional Benefits:
- The market estimate (ME) sheet in Excel format
- 3 months of analyst support
TABLE OF CONTENTS
1 INTRODUCTION
- 1.1 Study Assumptions and Market Definition
- 1.2 Scope of the Study
2 RESEARCH METHODOLOGY
3 EXECUTIVE SUMMARY
4 MARKET LANDSCAPE
- 4.1 Market Overview
- 4.2 Market Drivers
- 4.2.1 Generative AI Training Data Shortages
- 4.2.2 Privacy-Preserving Access to Sensitive Enterprise Data
- 4.2.3 Rising Demand for AI Model Testing and Validation
- 4.2.4 Autonomous Systems and Digital-Twin Simulation
- 4.2.5 Enterprise Data-Productization Workflows
- 4.2.6 Synthetic Data Benchmarking for Underrepresented and Long-Tail Events
- 4.3 Market Restraints
- 4.3.1 High Compute and Infrastructure Costs
- 4.3.2 Uncertain Legal Treatment of Synthetic Data
- 4.3.3 Synthetic-to-Synthetic Model Collapse
- 4.3.4 Hidden Leakage Through Metadata and Rare Records
- 4.4 Impact of Macroeconomic Factors on the Market
- 4.5 Industry Value-Chain Analysis
- 4.6 Technology Outlook
- 4.7 Regulatory Landscape
- 4.8 Porter's Five Forces Analysis
- 4.8.1 Threat of New Entrants
- 4.8.2 Bargaining Power of Suppliers
- 4.8.3 Bargaining Power of Buyers
- 4.8.4 Threat of Substitutes
- 4.8.5 Intensity of Competitive Rivalry
5 MARKET SIZE AND GROWTH FORECASTS (VALUE)
- 5.1 By Data Type
- 5.1.1 Tabular Data
- 5.1.2 Text and Natural Language Processing Data
- 5.1.3 Image and Video Data
- 5.1.4 Other Data Type
- 5.2 By Offering
- 5.2.1 Synthetic Data Generation Platforms
- 5.2.2 Professional and Managed Services
- 5.3 By Application
- 5.3.1 AI and Machine Learning Training and Development
- 5.3.2 Test Data Management
- 5.3.3 Data Sharing and Monetization
- 5.3.4 Data Analytics and Visualization
- 5.3.5 Autonomous Systems and Robotics Simulation
- 5.3.6 Other Applications
- 5.4 By End-User Industry
- 5.4.1 Banking, Financial Services and Insurance
- 5.4.2 Healthcare and Life Sciences
- 5.4.3 Automotive and Transportation
- 5.4.4 Retail and E-Commerce
- 5.4.5 Information Technology and Telecommunications
- 5.4.6 Manufacturing and Industrial Automation
- 5.4.7 Other End-User Industries
- 5.5 By Geography
- 5.5.1 North America
- 5.5.1.1 United States
- 5.5.1.2 Canada
- 5.5.1.3 Mexico
- 5.5.2 South America
- 5.5.2.1 Brazil
- 5.5.2.2 Argentina
- 5.5.2.3 Chile
- 5.5.2.4 Rest of South America
- 5.5.3 Europe
- 5.5.3.1 Germany
- 5.5.3.2 United Kingdom
- 5.5.3.3 France
- 5.5.3.4 Italy
- 5.5.3.5 Spain
- 5.5.3.6 Rest of Europe
- 5.5.4 Asia-Pacific
- 5.5.4.1 China
- 5.5.4.2 Japan
- 5.5.4.3 India
- 5.5.4.4 South Korea
- 5.5.4.5 Australia
- 5.5.4.6 Rest of Asia-Pacific
- 5.5.5 Middle East
- 5.5.5.1 United Arab Emirates
- 5.5.5.2 Saudi Arabia
- 5.5.5.3 Qatar
- 5.5.5.4 Rest of Middle East
- 5.5.6 Africa
- 5.5.6.1 South Africa
- 5.5.6.2 Egypt
- 5.5.6.3 Nigeria
- 5.5.6.4 Rest of Africa
- 5.5.1 North America
6 COMPETITIVE LANDSCAPE
- 6.1 Market Concentration
- 6.2 Strategic Moves
- 6.3 Market Share Analysis
- 6.4 Company Profiles (includes Global Level Overview, Market Level Overview, Core Segments, Financials as available, Strategic Information, Market Rank/Share, Products and Services, Recent Developments)
- 6.4.1 Amazon Web Services, Inc.
- 6.4.2 Microsoft Corporation
- 6.4.3 NVIDIA Corporation
- 6.4.4 Google Inc
- 6.4.5 International Business Machines Corporation
- 6.4.6 Databricks, Inc.
- 6.4.7 MOSTLY AI GmbH
- 6.4.8 Gretel Labs, Inc.
- 6.4.9 Synthesis AI, Inc.
- 6.4.10 Tonic AI, Inc.
- 6.4.11 GenRocket, Inc.
- 6.4.12 Hazy Limited
- 6.4.13 Datagen Technologies Ltd.
- 6.4.14 Parallel Domain, Inc.
- 6.4.15 Rendered.ai, Inc.
- 6.4.16 MDClone Ltd.
- 6.4.17 Syntho B.V.
- 6.4.18 Betterdata Pte. Ltd.
- 6.4.19 K2view Ltd.
- 6.4.20 Informatica Inc.
- 6.4.21 Sogeti S.A.
7 MARKET OPPORTUNITIES AND FUTURE OUTLOOK
- 7.1 White-Space and Unmet-Need Assessment

