PUBLISHER: Mordor Intelligence | PRODUCT CODE: 2154334

PUBLISHER: Mordor Intelligence | PRODUCT CODE: 2154334
RAG Evaluation Platforms - Market Share Analysis, Industry Trends & Statistics, Growth Forecasts (2026 - 2031)
According to Mordor Intelligence, the RAG evaluation platforms market size is projected to expand from USD 25.22 billion in 2025 and USD 30.81 billion in 2026 to USD 83.21 billion by 2031, registering a CAGR of 21.98% between 2026 to 2031.
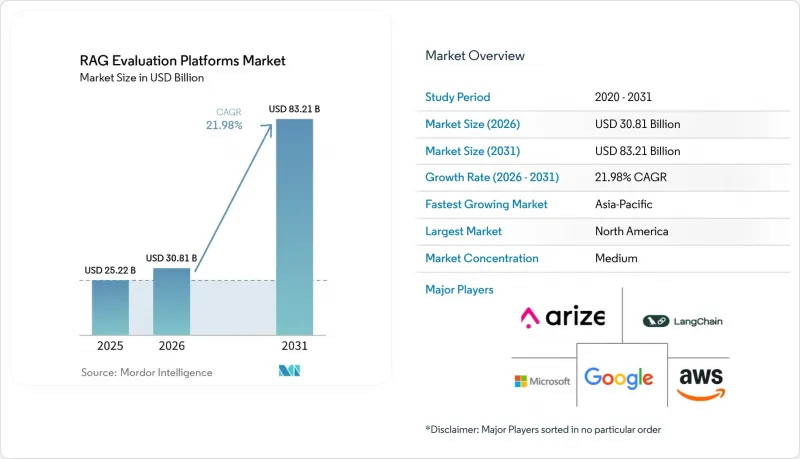
Global RAG Evaluation Platforms Market Trends and Insights
Enterprise GenAI Productionization
The move from prototypes into production is a central driver for the RAG evaluation platforms market. Retrieval systems can develop silent failures after launch, including retrieval degradation, embedding drift, prompt regressions, changing source collections, and unexpected variations in live user queries. Teams therefore need continuous checks rather than a single quality review before deployment, especially when models, prompts, retrieval settings, or underlying documents are updated. Evaluation gates in delivery pipelines make each system change subject to defined quality thresholds. This operating model turns evaluation from a one-time implementation activity into a recurring platform requirement. Arize AI secured USD 70 million in Series C financing in February 2025, showing continued investment interest in AI observability and evaluation capabilities.
Regulatory Demand for Traceable AI Quality Evidence
The RAG evaluation platforms market benefits when organizations need documented evidence of how an AI system performed. The EU AI Act creates requirements for record keeping, documentation, and human oversight for high-risk systems. These requirements apply from August 2026 under the Act's phased timetable. RAG workflows that influence consequential decisions need logs that can show retrieved evidence, evaluation results, system changes, review decisions, and the applicable version of each control. Compliance teams also need evaluation methods that can be explained during internal reviews and external assessments without relying on undocumented model judgments or opaque scoring rules. ISO/IEC 42001 supports this direction by establishing requirements for an AI management system, including governance processes that can support structured evaluation.
Evaluator Bias and LLM-as-a-Judge Instability
LLM-based judges automate many evaluation tasks, but their reliability remains a restraint for the RAG evaluation platforms market. IBM Research identified 12 bias categories in LLM-based judges, including position bias, verbosity preference, and self-preference. These effects can make a score depend on presentation choices rather than the underlying quality of the answer. Buyers often respond by using multiple judge models, human calibration, or consistency checks. Those safeguards improve confidence but increase cost and operational complexity because teams must maintain reviewer guidance, reconcile conflicting scores, and repeat tests across important scenarios. The issue is especially important in financial services and healthcare, where an evaluation result must withstand closer scrutiny.
Other drivers and restraints analyzed in the detailed report include:
- Expansion of Agentic and Multi-Step RAG Workflows
- OpenTelemetry Standardization of AI Application Telemetry
- Scarcity of Domain-Specific Ground-Truth Data
For complete list of drivers and restraints, kindly check the Table Of Contents.
Segment Analysis
Software held 69.82% of the share in 2025. Enterprises commonly purchase software for scorecards, trace review, experiment management, and deployment controls within a single environment. This model supports recurring licenses and allows teams to standardize evaluation across multiple applications. Software revenue can also include platform functions that support substantial advisory work, including implementation support, metric selection, data preparation, reviewer calibration, and governance documentation. That classification can conceal the amount of specialized configuration required in real deployments.
Services are projected to grow at a 22.73% CAGR through 2031, which is slightly above the overall RAG evaluation platforms market growth rate. Organizations need support to create evaluation datasets, calibrate judges against human reviewers, and integrate controls into software delivery workflows. They also need custom measures for clinical, legal, and financial content. Braintrust provides workflows that help users develop scores and datasets from production traces. Even where automation is available, initial configuration and governance design remain material services requirements.
Cloud represented 57.28% of the RAG evaluation platforms market size in 2025. It is also the fastest-growing segment, with a CAGR of 22.76% through 2031. Cloud delivery provides organizations with elastic capacity for large trace volumes and eliminates the need to operate evaluation infrastructure internally. It also matches the purchasing model of organizations that already run models and retrieval services in cloud environments. AWS introduced RAG evaluation capabilities for Amazon Bedrock agents in December 2024. Google also made agent and model evaluations generally available for its Gemini Enterprise Agent Platform in 2025.
On-premises deployment remains relevant for government and financial services users who cannot send sensitive documents to external evaluation interfaces. Hybrid models provide another option by keeping retrieved content within enterprise environments while sending selected metadata and scores to dashboards. This design lets organizations balance data residency requirements with central oversight, while allowing security, compliance, and engineering teams to work from a consistent view of performance. Databricks documented an integration that exports Langfuse traces to MLflow through OpenTelemetry endpoints. The RAG evaluation platforms market, therefore, includes deployment choices that reflect both technical scale and data-handling constraints.
Complete Report Scope:
- By Component
- Software
- Services
- By Deployment Mode
- Cloud
- On-Premises
- Hybrid
- By Evaluation Function
- Retrieval Quality
- Generation Quality
- Safety, Security, and Responsible AI
- Operational and Economic Performance
- By End User
- Banking, Financial Services, and Insurance
- Healthcare and Life Sciences
- IT and Telecommunications
- Retail and E-commerce
- Other End Users
- By Geography
- North America
- United States
- Canada
- Mexico
- South America
- Brazil
- Argentina
- Rest of South America
- Europe
- United Kingdom
- Germany
- France
- Italy
- Spain
- Russia
- Rest of Europe
- Asia-Pacific
- China
- Japan
- South Korea
- India
- Australia
- Rest of Asia-Pacific
- Middle East
- United Arab Emirates
- Saudi Arabia
- Turkey
- Rest of Middle East
- Africa
- South Africa
- Kenya
- Rest of Africa
- North America
Geography Analysis
North America held 48.27% of share in 2025. The region has a large concentration of generative AI adopters, venture-backed specialists, and established MLOps tools. It also includes cloud providers that are embedding evaluation functions in broader AI platforms. Arize AI raised USD 70 million in February 2025 to expand its AI evaluation and observability offering. OpenTelemetry conventions can further reduce integration effort for organizations using several tools. Canada contributes through financial services and public-sector programs that require evidence for AI governance decisions.
Europe is the second-largest regional market, supported by regulatory demand for documented AI controls. The EU AI Act makes traceability, documentation, and oversight more important for high-risk uses from August 2026. Banks, insurers, health agencies, and public bodies must therefore consider how they will demonstrate system behaviour. Germany and France contribute academic evaluation research that can support commercial development. The United Kingdom, Germany, France, Italy, and Spain are important adoption locations. South America is at an earlier stage, with financial services users in Brazil beginning to adopt RAG tools for customer service and internal knowledge work.
Asia-Pacific is forecast to grow at a 22.63% CAGR through 2031. India's financial technology sector creates demand for safety testing before new RAG applications reach production. Japan has developed public benchmarking resources for legal content, including the lawqa_jp dataset published in 2025. China's domestic model ecosystem creates demand for comparison and evaluation across rapidly changing model families. The Middle East is introducing RAG evaluation within national AI programs, especially in the UAE and Saudi Arabia. Africa remains at an earlier stage, with adoption linked to broader digital and cloud infrastructure development.
- Arize, Inc.
- LangChain, Inc.
- Databricks, Inc.
- Snowflake Inc.
- Weights & Biases, Inc.
- Braintrust Data, Inc.
- Confident AI, Inc.
- Evidently AI, Inc.
- Langfuse GmbH
- Promptfoo, Inc.
- TruEra, Inc.
- HoneyHive, Inc.
- Openlayer, Inc.
- Helicone, Inc.
- Appen Limited
- Vecta AI, Inc.
- Fiddler AI, Inc.
- DataRobot, Inc.
- Microsoft Corporation
- Amazon Web Services, Inc.
- Google LLC
- IBM Corporation
- NVIDIA Corporation
- Scale AI, Inc.
- Pinecone Systems, Inc.
- Zilliz, Inc.
- Qdrant Solutions GmbH
- Weaviate B.V.
- Redis Ltd.
- Chroma, Inc.
- LlamaIndex, Inc.
Additional Benefits:
- The market estimate (ME) sheet in Excel format
- 3 months of analyst support
TABLE OF CONTENTS
1 INTRODUCTION
- 1.1 Study Assumptions and Market Definition
- 1.2 Scope of the Study
2 RESEARCH METHODOLOGY
3 EXECUTIVE SUMMARY
4 MARKET LANDSCAPE
- 4.1 Market Overview
- 4.2 Market Drivers
- 4.2.1 Enterprise GenAI Productionization
- 4.2.2 Regulatory Demand for Traceable AI Quality Evidence
- 4.2.3 Expansion of Agentic and Multi-Step RAG Workflows
- 4.2.4 Rising Cost of Uncaught Retrieval and Grounding Failures
- 4.2.5 OpenTelemetry Standardization of AI Application Telemetry
- 4.2.6 Shift From Offline Benchmarks to Continuous Production Evaluation
- 4.3 Market Restraints
- 4.3.1 Evaluator Bias and LLM-as-a-Judge Instability
- 4.3.2 Scarcity of Domain-Specific Ground-Truth Data
- 4.3.3 Evaluation Token Cost and Inference Latency
- 4.3.4 Fragmented Instrumentation Across RAG Stacks
- 4.4 Industry Value / Supply-Chain Analysis
- 4.5 Regulatory Landscape
- 4.6 Technological Outlook
- 4.7 Porter's Five Forces Analysis
- 4.7.1 Intensity of Competitive Rivalry
- 4.7.2 Threat of New Entrants
- 4.7.3 Bargaining Power of Suppliers
- 4.7.4 Bargaining Power of Buyers
- 4.7.5 Threat of Substitutes
5 MARKET SIZE AND GROWTH FORECASTS (VALUE)
- 5.1 By Component
- 5.1.1 Software
- 5.1.2 Services
- 5.2 By Deployment Mode
- 5.2.1 Cloud
- 5.2.2 On-Premises
- 5.2.3 Hybrid
- 5.3 By Evaluation Function
- 5.3.1 Retrieval Quality
- 5.3.2 Generation Quality
- 5.3.3 Safety, Security, and Responsible AI
- 5.3.4 Operational and Economic Performance
- 5.4 By End User
- 5.4.1 Banking, Financial Services, and Insurance
- 5.4.2 Healthcare and Life Sciences
- 5.4.3 IT and Telecommunications
- 5.4.4 Retail and E-commerce
- 5.4.5 Other End Users
- 5.5 By Geography
- 5.5.1 North America
- 5.5.1.1 United States
- 5.5.1.2 Canada
- 5.5.1.3 Mexico
- 5.5.2 South America
- 5.5.2.1 Brazil
- 5.5.2.2 Argentina
- 5.5.2.3 Rest of South America
- 5.5.3 Europe
- 5.5.3.1 United Kingdom
- 5.5.3.2 Germany
- 5.5.3.3 France
- 5.5.3.4 Italy
- 5.5.3.5 Spain
- 5.5.3.6 Russia
- 5.5.3.7 Rest of Europe
- 5.5.4 Asia-Pacific
- 5.5.4.1 China
- 5.5.4.2 Japan
- 5.5.4.3 South Korea
- 5.5.4.4 India
- 5.5.4.5 Australia
- 5.5.4.6 Rest of Asia-Pacific
- 5.5.5 Middle East
- 5.5.5.1 United Arab Emirates
- 5.5.5.2 Saudi Arabia
- 5.5.5.3 Turkey
- 5.5.5.4 Rest of Middle East
- 5.5.6 Africa
- 5.5.6.1 South Africa
- 5.5.6.2 Kenya
- 5.5.6.3 Rest of Africa
- 5.5.1 North America
6 COMPETITIVE LANDSCAPE
- 6.1 Market Concentration
- 6.2 Strategic Moves
- 6.3 Market Share Analysis
- 6.4 Company Profiles (includes Global Level Overview, Market Level Overview, Core Segments, Financials as available, Strategic Information, Market Rank/Share, Products and Services, Recent Developments)
- 6.4.1 Arize, Inc.
- 6.4.2 LangChain, Inc.
- 6.4.3 Databricks, Inc.
- 6.4.4 Snowflake Inc.
- 6.4.5 Weights & Biases, Inc.
- 6.4.6 Braintrust Data, Inc.
- 6.4.7 Confident AI, Inc.
- 6.4.8 Evidently AI, Inc.
- 6.4.9 Langfuse GmbH
- 6.4.10 Promptfoo, Inc.
- 6.4.11 TruEra, Inc.
- 6.4.12 HoneyHive, Inc.
- 6.4.13 Openlayer, Inc.
- 6.4.14 Helicone, Inc.
- 6.4.15 Appen Limited
- 6.4.16 Vecta AI, Inc.
- 6.4.17 Fiddler AI, Inc.
- 6.4.18 DataRobot, Inc.
- 6.4.19 Microsoft Corporation
- 6.4.20 Amazon Web Services, Inc.
- 6.4.21 Google LLC
- 6.4.22 IBM Corporation
- 6.4.23 NVIDIA Corporation
- 6.4.24 Scale AI, Inc.
- 6.4.25 Pinecone Systems, Inc.
- 6.4.26 Zilliz, Inc.
- 6.4.27 Qdrant Solutions GmbH
- 6.4.28 Weaviate B.V.
- 6.4.29 Redis Ltd.
- 6.4.30 Chroma, Inc.
- 6.4.31 LlamaIndex, Inc.
7 MARKET OPPORTUNITIES AND FUTURE OUTLOOK
- 7.1 White-Space and Unmet-Need Assessment

